← All writing 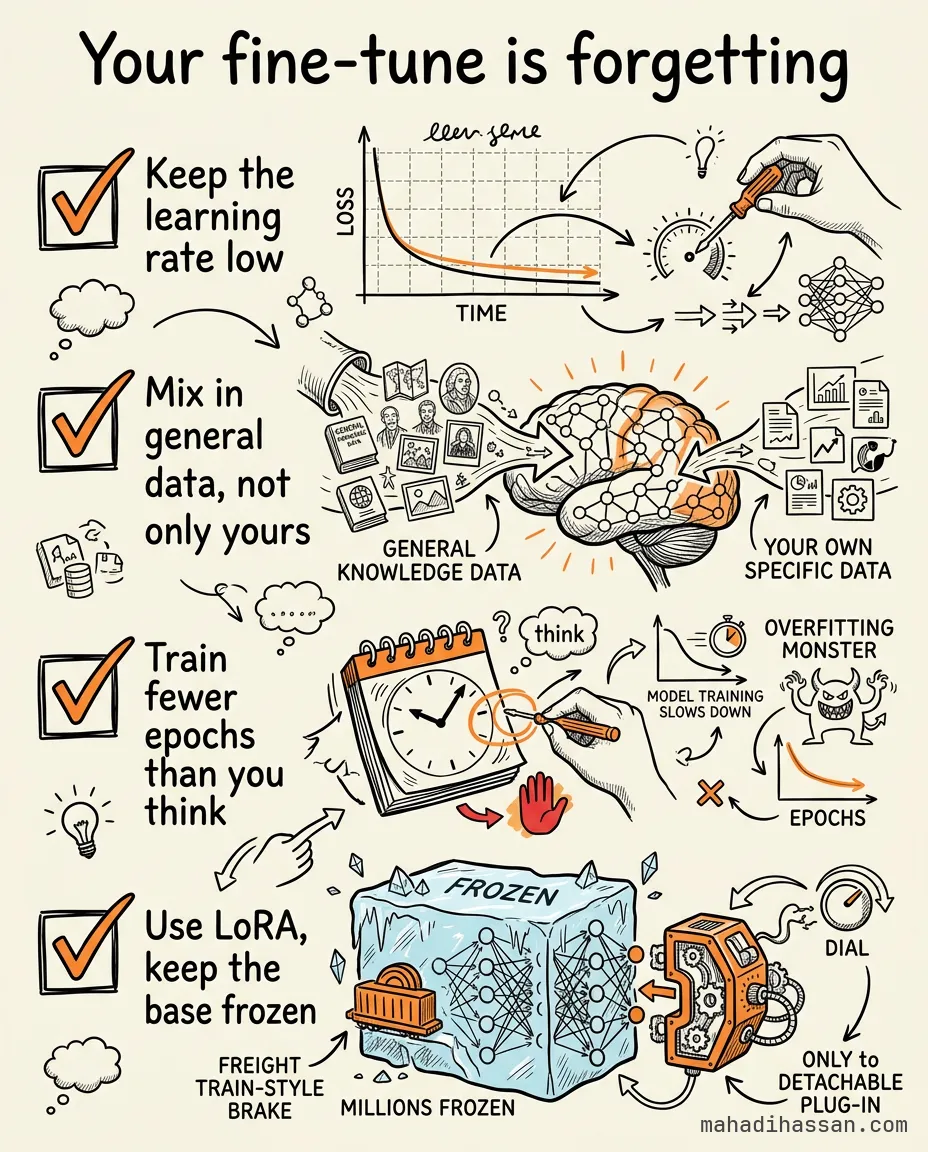
FIELD NOTES
Your fine-tune is forgetting
2026-07-15
You fine-tuned your model, and somehow it came out dumber.
Better at your one task. Worse at things it used to do well.
That’s not a fluke. It has a name: catastrophic forgetting.
When you train a model hard on a narrow slice of data, it overwrites some of the general ability it shipped with.
You taught it your support tickets. It quietly got worse at reasoning, at formatting, at the basics it used to nail.
The fixes aren’t exotic:
- Keep the learning rate low. Big updates overwrite more.
- Mix in general data, not only your task data.
- Train fewer epochs than you think. More passes isn’t more learning — it’s more forgetting.
- Prefer adapters like LoRA over full fine-tuning. The base model stays frozen, so there’s far less to forget.
A fine-tune that wins your task but loses everything else is not a win.
It’s a trade you probably didn’t mean to make.