← All writing 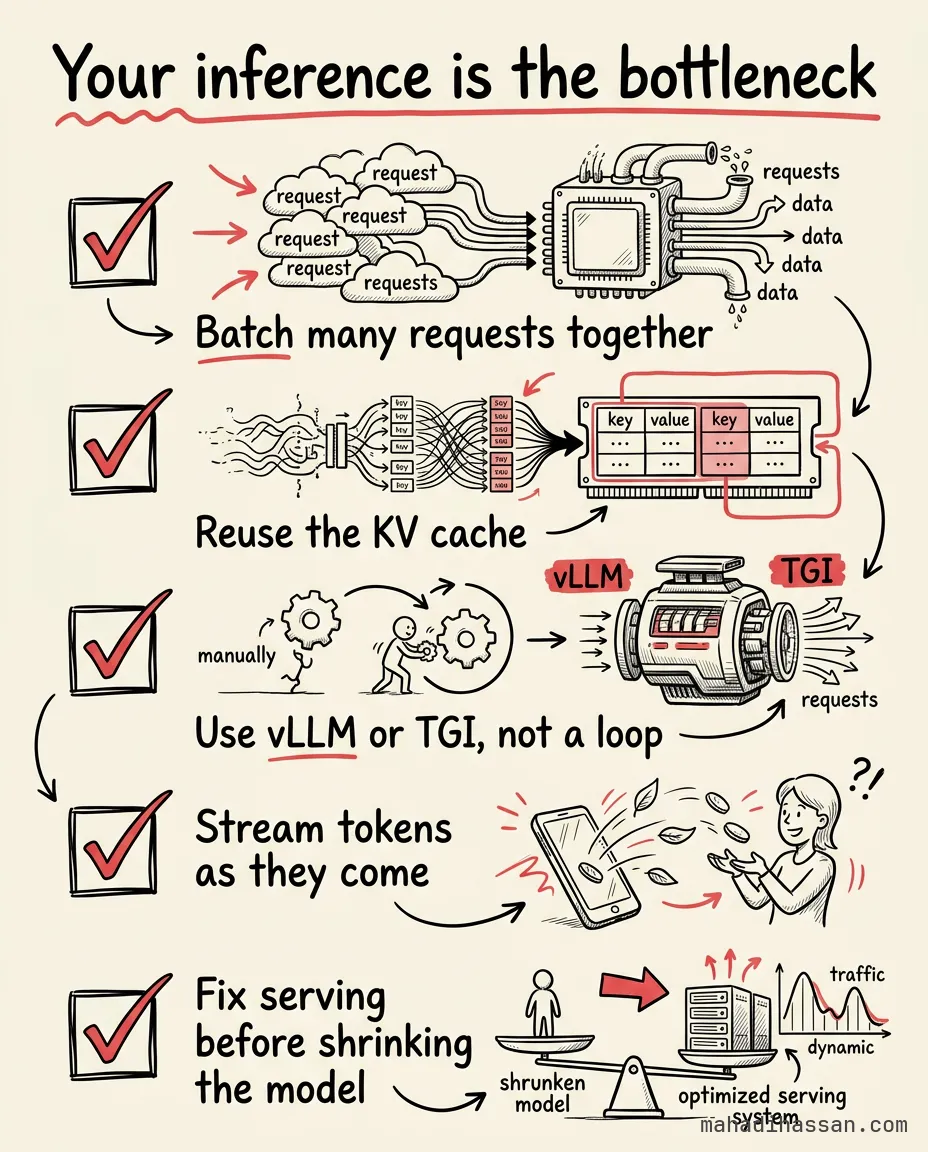
FIELD NOTES
Your inference is the bottleneck
2026-07-15
Your AI feature feels slow, so you reach for a smaller model.
Often the model was never the problem. The way you run it is.
Same model, same hardware — inference setup alone can swing latency and cost by 5 to 10 times.
The usual wins:
- Batching — serve many requests together instead of one at a time. Huge throughput gain.
- KV cache — stop recomputing attention for tokens you already processed.
- A real serving engine — vLLM or TGI instead of a naive loop. This alone is often the biggest jump.
- Streaming — send tokens as they’re generated. It feels fast even when the total time is the same.
Before you downgrade the model, fix how you’re serving it.
Most “slow model” problems are slow plumbing.